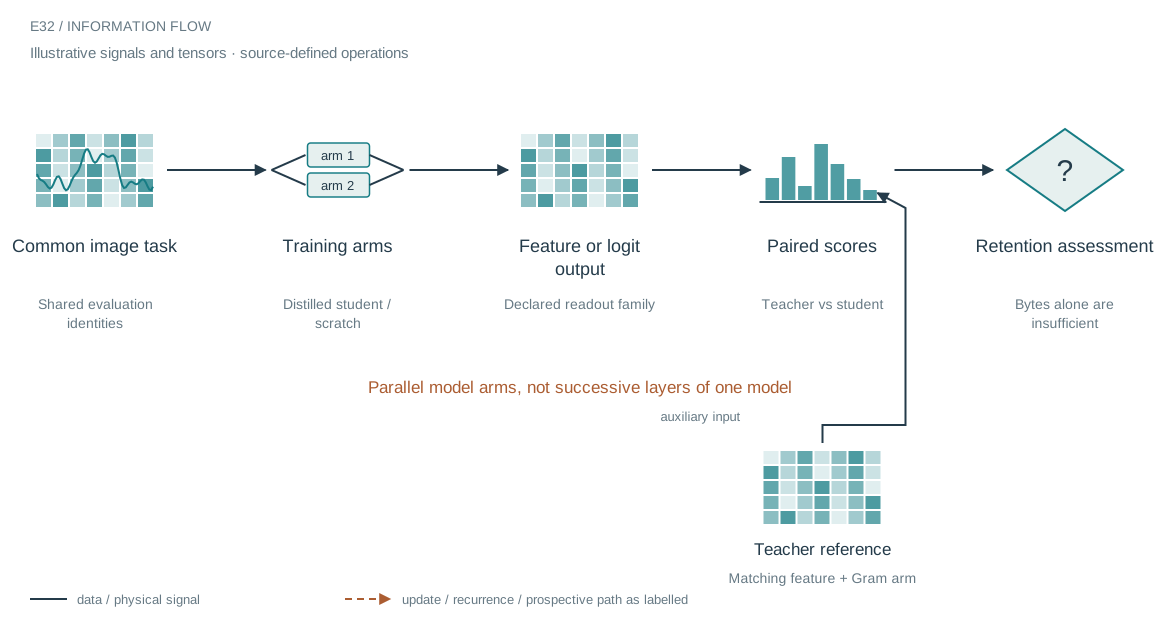
The architecture in context
What this comparison asks
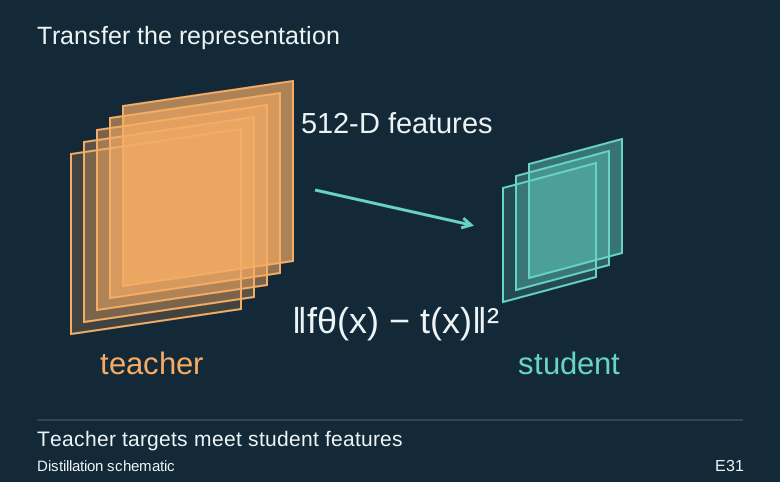
The saved compact-student experiment asks whether a lightweight CNN can inherit a stronger representation. It reports parameter count alongside downstream scores and feature MSE. That is the right direction for compression evaluation: a byte or parameter reduction only becomes useful when the desired capability survives.
Who does what in the stack
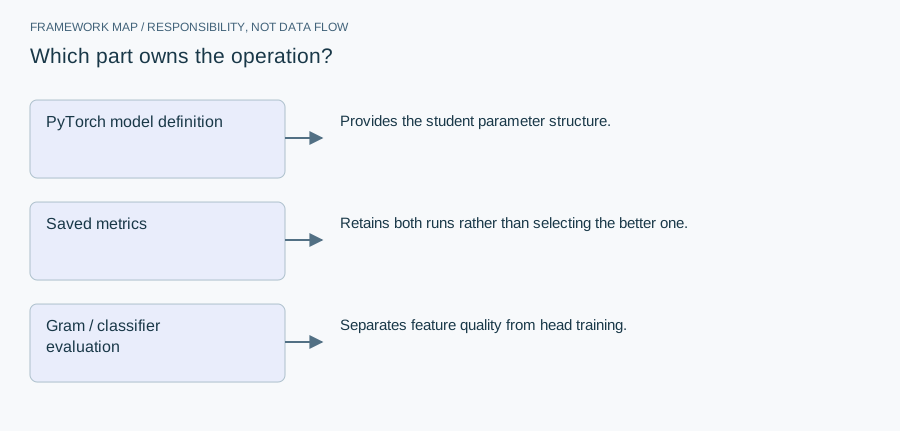
- PyTorch model definition
- Provides the student parameter structure.
- Saved metrics
- Retains both runs rather than selecting the better one.
- Gram / classifier evaluation
- Separates feature quality from head training.
The primary artifact is a metrics record; the displayed companion code defines the student architecture. Keeping those roles distinct avoids presenting a network diagram as evidence that the network worked. The count includes the archived model’s parameters, not a measured packed deployment footprint.
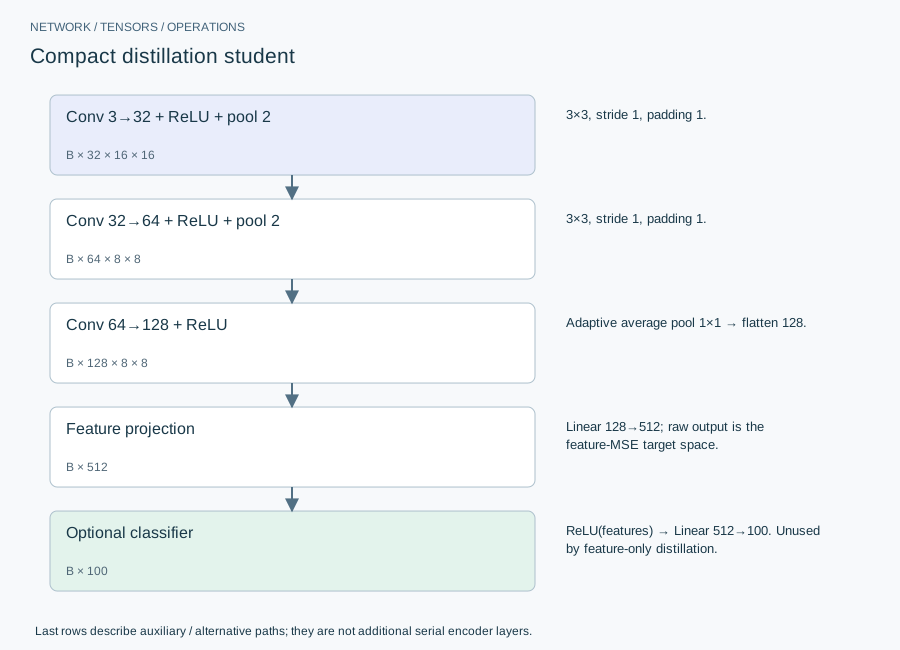
From module map to executable structure
Inside Compact distillation student
This results or evaluation article shares the implementation in E31. The architecture below describes that companion, not a newly trained model.
CIFAR-100 images 3×32×32; teacher feature width 512; student classifier 100 classes.
| Layer or branch | Output shape | Implementation detail |
|---|---|---|
| Conv 3→32 + ReLU + pool 2 | B × 32 × 16 × 16 | 3×3, stride 1, padding 1. |
| Conv 32→64 + ReLU + pool 2 | B × 64 × 8 × 8 | 3×3, stride 1, padding 1. |
| Conv 64→128 + ReLU | B × 128 × 8 × 8 | Adaptive average pool 1×1 → flatten 128. |
| Feature projection | B × 512 | Linear 128→512; raw output is the feature-MSE target space. |
| Optional classifier | B × 100 | ReLU(features) → Linear 512→100. Unused by feature-only distillation. |
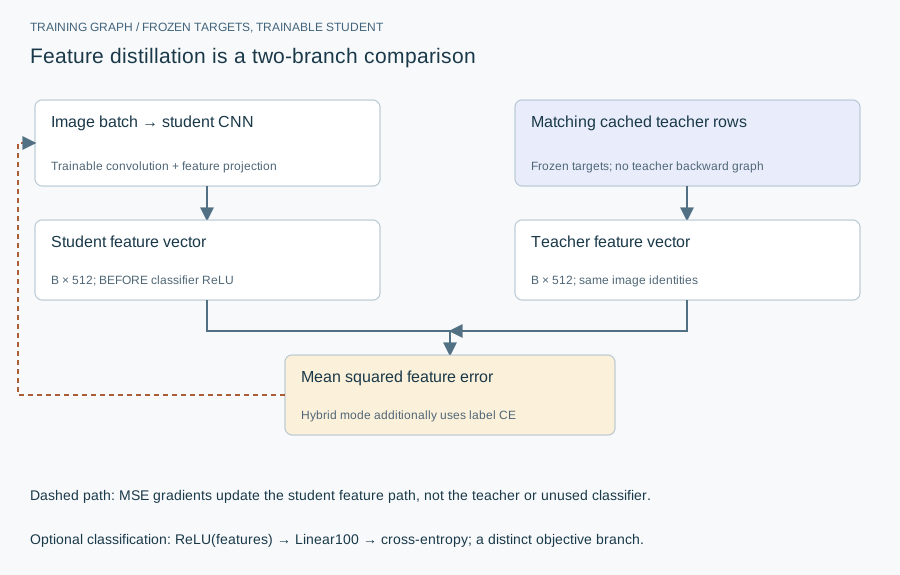
The teacher features are cached targets, so the teacher is not in the student’s backward graph. The feature projection is linear; applying its later classifier ReLU before computing MSE would change the experiment. Downstream Gram evaluation uses frozen features and must be reported separately from the student’s direct classifier accuracy.
The equation and the update
Adam 1e-3, batch 256; default 8 epochs, two seeds. Feature-only loss is MSE; hybrid adds supervised cross-entropy; scratch uses cross-entropy alone. These objectives update different parts of the same allocated model.
Implementation card / no invented benchmarks
Capacity, budget and execution evidence
- Parameters / retained state
- 210,596 allocated scalars; 51,300 classifier scalars receive no gradient in feature-only mode. The feature path has 159,296.
- Duration and hardware evidence
- The training function returns elapsed time, but E32’s JSON does not retain it; no duration is supplied as if measured.
- Source coordinates
- E31 lines 34–42, 71–91; E32 saved metrics
- Current reproduction context
- Current workstation, supplied by the author: Apple M4, 128 GB unified RAM, 40 GPU cores and 16 CPU cores. This is context for prospective reproduction, not attribution of every archived run. Python and framework versions are not fully locked for these historical sources; declarations, when available, are identified separately.
Counts above are calculated from the stated layer shapes unless identified as saved measurements. They exclude optimizer state and nontrainable buffers. No archived training was rerun for this revision.
What these design choices change
Global pooling makes the feature projection much smaller than flattening the last spatial map. A512-wide representation is chosen to match the teacher target, not because every student needs 512 features. Reducing it requires a new teacher projection or a different distillation objective.
Reproduction and measurement protocol
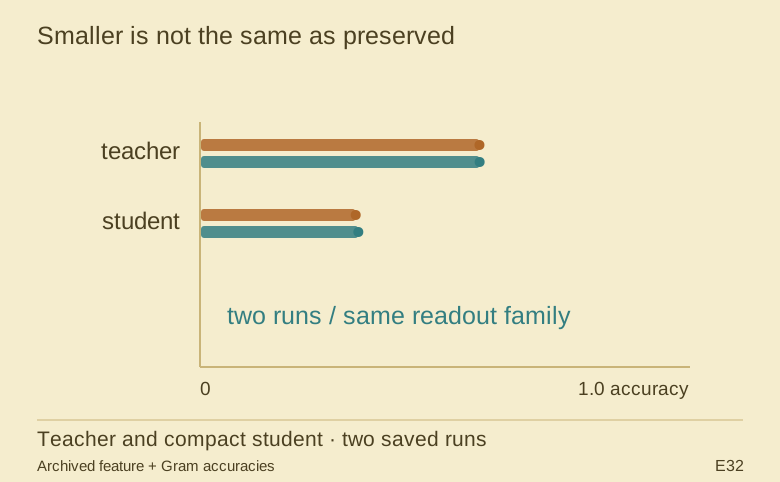
Assert teacher/student row identity before comparing features; cached targets in a different shuffle order create a valid-shaped but meaningless loss. Check classifier gradients are absent in feature-only mode. The saved teacher-to-student accuracy gap shows that parameter reduction did not preserve the teacher’s usefulness.
For a new run, save the resolved Python/framework versions, backend, dtype, seed, input shapes, batch size and exact source revision. Start with one batch and one update. Log training steps separately from epochs or environment steps. Do not equate the configured maximum with a completed budget or convergence.
Measure initialization/compilation, data preparation, warmed forward pass, training updates and evaluation separately. Synchronize accelerator work around timed regions using the chosen framework’s supported mechanism. Report peak process memory and framework allocation separately; parameter bytes exclude activations, gradients, optimizer state and input buffers. On a shared machine, begin with a single CPU worker and a small batch rather than claiming all available resources.
A closer look at the implementation
The code that carries the idea
The student uses convolutional channels 32, 64 and 128, then a 512-dimensional projection and a 100-class head. Saved teacher-feature Gram accuracies are 0.5862 and 0.5866; the distilled student’s Gram accuracies are 0.3257 and 0.3312. Scratch classification reaches 0.3545 and 0.3675.
class StudentCNN(nn.Module):
    def __init__(self, out=512, nclass=100):
        super().__init__()
        self.enc = nn.Sequential(nn.Conv2d(3, 32, 3, 1, 1), nn.ReLU(), nn.MaxPool2d(2),
                                 nn.Conv2d(32, 64, 3, 1, 1), nn.ReLU(), nn.MaxPool2d(2),
                                 nn.Conv2d(64, 128, 3, 1, 1), nn.ReLU(), nn.AdaptiveAvgPool2d(1), nn.Flatten())
        self.feat = nn.Linear(128, out); self.cls = nn.Linear(out, nclass)
    def features(self, x): return self.feat(self.enc(x))
    def forward(self, x): return self.cls(torch.relu(self.features(x)))
Verbatim archive excerpt from closed_form_distill_v3_compact.py (companion source E31). Context-dependent historical code, not a standalone runnable program. Comments retain their original wording; the article distinguishes implemented behavior from stale or overbroad comments.
The saved comparison
Archived results, not new training. The article states the comparison’s scope and limitations.
| Arm | Run 1 | Run 2 |
|---|---|---|
| Teacher features + Gram | 0.5862 | 0.5866 |
| Distilled student + Gram | 0.3257 | 0.3312 |
| Scratch classifier | 0.3545 | 0.3675 |
The boundary that matters
The student did not preserve teacher capability in this setting, and the reported distillation arm does not establish an advantage over scratch classification. Two saved runs are not enough to characterize a broad distillation frontier. Feature MSE also needs its normalization convention to be interpretable.