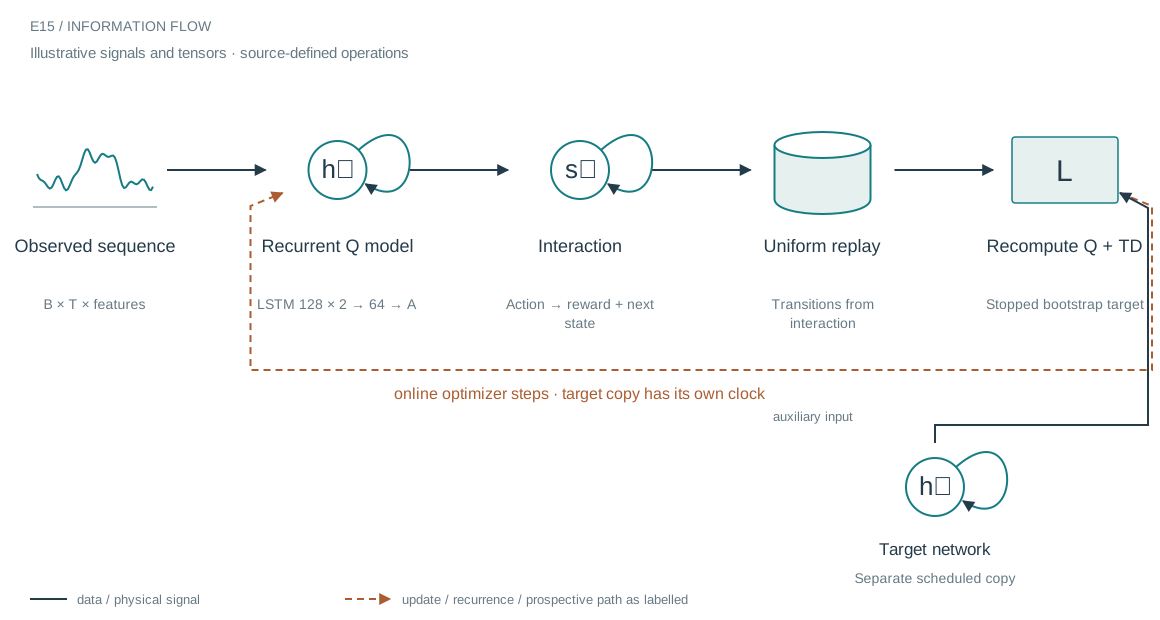
The architecture in context
The system we are building
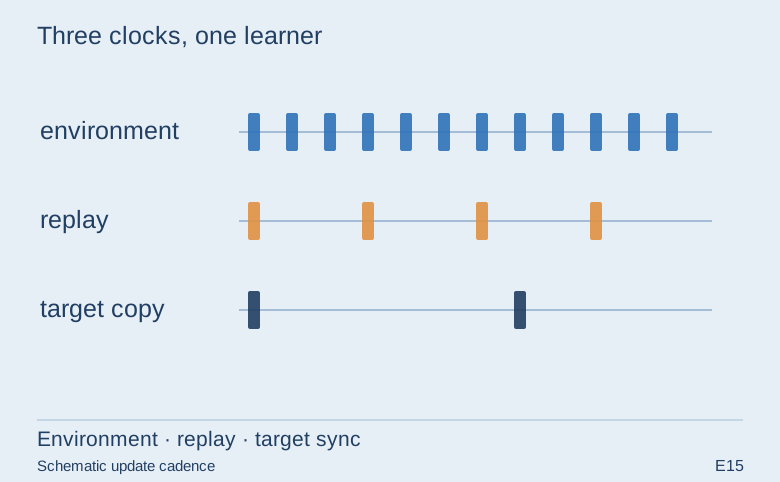
The earlier agent uses two LSTMs, the final temporal state and a small dense head to estimate an action value vector. An epsilon-greedy rule chooses actions. Transitions enter a bounded deque, while training samples them uniformly. The target network is initialized from the online network and synchronized separately.
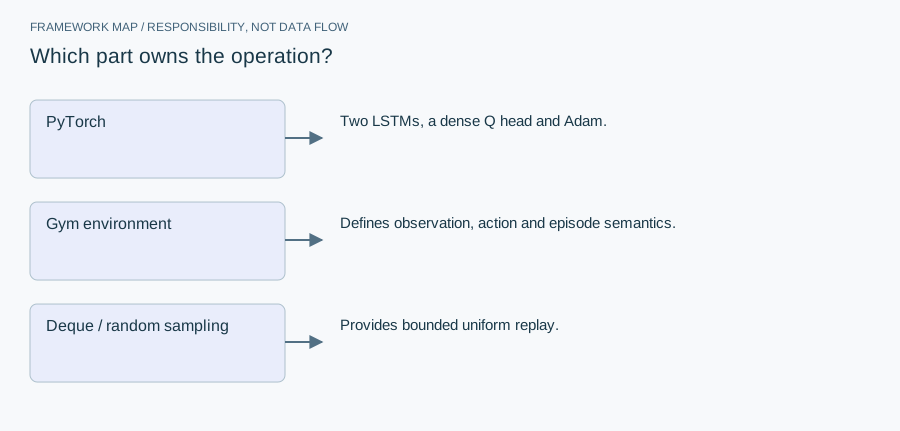
Who does what in the stack
- PyTorch
- Two LSTMs, a dense Q head and Adam.
- Gym environment
- Defines observation, action and episode semantics.
- Deque / random sampling
- Provides bounded uniform replay.
The notebook builds a custom Gym environment and connects its observation shape to a recurrent PyTorch model. It explicitly handles device placement, replay batching and target computation. The useful abstraction is not “an LSTM trades”; it is a policy-learning loop whose data, update and synchronization events can be inspected independently.
From module map to executable structure
Inside Recurrent Q-network
This results or evaluation article shares the implementation in E14. The architecture below describes that companion, not a newly trained model.
Two single-layer PyTorch LSTMs, hidden 128; configurable observation and action dimensions.
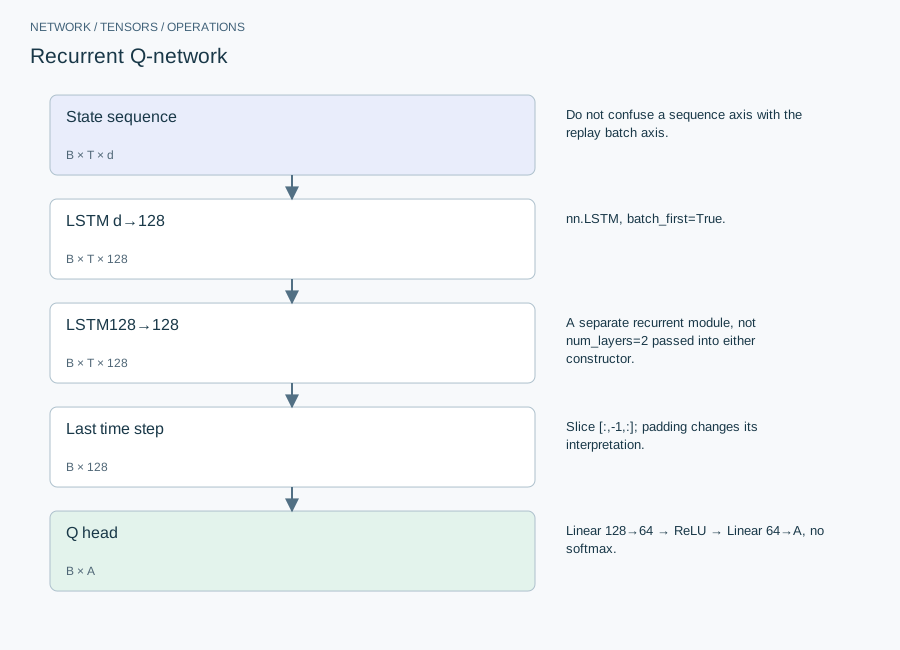
| Layer or branch | Output shape | Implementation detail |
|---|---|---|
| State sequence | B × T × d | Do not confuse a sequence axis with the replay batch axis. |
| LSTM d→128 | B × T × 128 | nn.LSTM, batch_first=True. |
| LSTM128→128 | B × T × 128 | A separate recurrent module, not num_layers=2 passed into either constructor. |
| Last time step | B × 128 | Slice [:,-1,:]; padding changes its interpretation. |
| Q head | B × A | Linear 128→64 → ReLU → Linear 64→A, no softmax. |
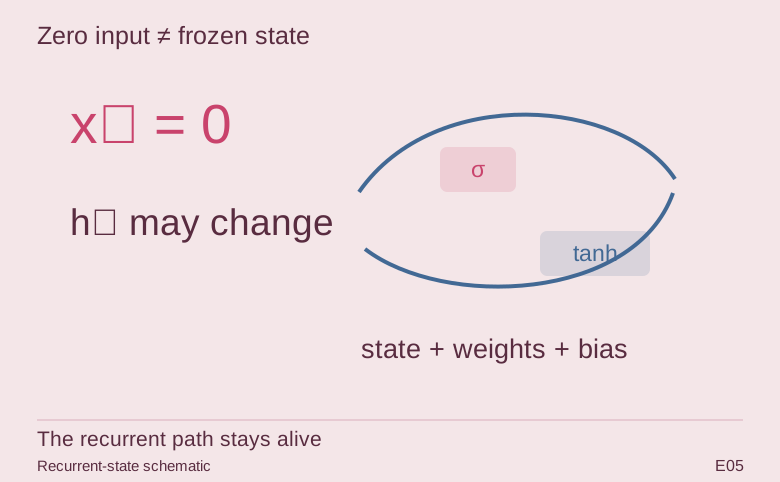
The recurrent encoder converts a window into one feature vector; the head estimates one action value per action, not action probabilities. The target network supplies a slowly changing bootstrap. Stop-gradient applies to the target, while only the taken action contributes to each sampled TD error.
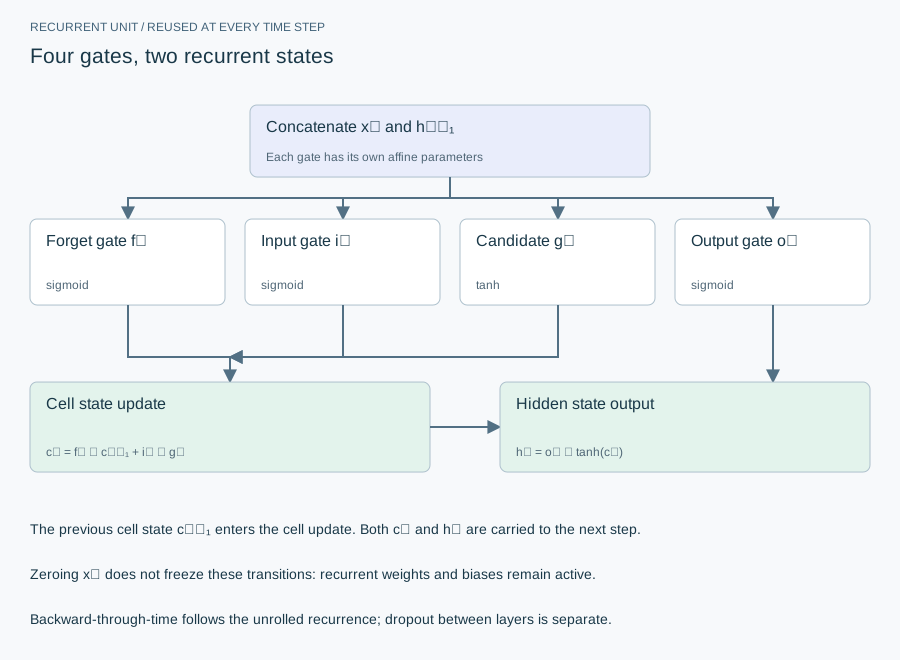
The equation and the update
Defaults: Adam 1e-3, gamma .99, replay 50,000 and batch 128. E14 adds prioritized replay and soft target updates (tau .005); E15 uses its own replay/target-update logic. They are not interchangeable training protocols.
Implementation card / no invented benchmarks
Capacity, budget and execution evidence
- Parameters / retained state
- 512(d+130)+512×258+8,256+65A per network, using PyTorch’s two bias vectors. Target network duplicates stored parameters.
- Duration and hardware evidence
- Archived examples are limited/interrupted runs; no convergence speed is inferred.
- Source coordinates
- E14 cell 2, lines 315–363; E15 cell 5, lines 39–80
- Current reproduction context
- Current workstation, supplied by the author: Apple M4, 128 GB unified RAM, 40 GPU cores and 16 CPU cores. This is context for prospective reproduction, not attribution of every archived run. Python and framework versions are not fully locked for these historical sources; declarations, when available, are identified separately.
Counts above are calculated from the stated layer shapes unless identified as saved measurements. They exclude optimizer state and nontrainable buffers. No archived training was rerun for this revision.
What these design choices change
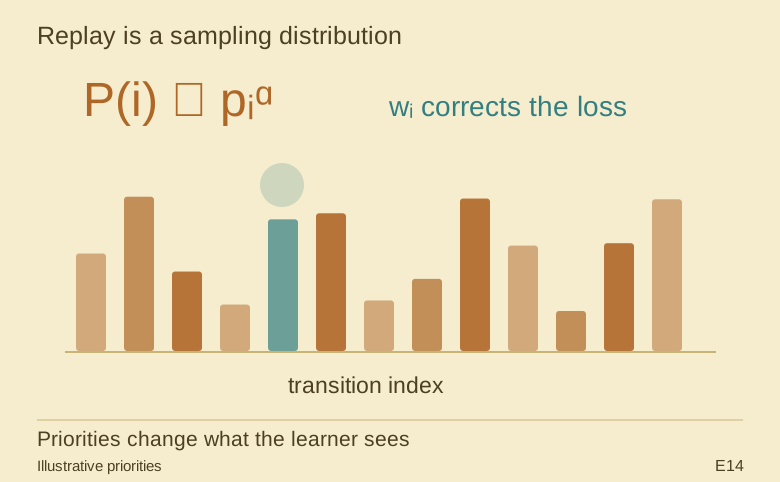
Longer windows enlarge unrolled activation memory without changing the count of recurrent weights. Prioritized replay changes the sample distribution, so importance weights belong inside the per-sample loss before reduction. A priority exponent and an importance exponent serve different purposes.
Reproduction and measurement protocol
Create one terminal and one nonterminal transition and calculate both targets by hand. Test that priority updates use the intended TD-error magnitude. For recurrent replay, declare whether hidden state is reset for each sampled window; state carried across unrelated samples is a different algorithm.
For a new run, save the resolved Python/framework versions, backend, dtype, seed, input shapes, batch size and exact source revision. Start with one batch and one update. Log training steps separately from epochs or environment steps. Do not equate the configured maximum with a completed budget or convergence.
Measure initialization/compilation, data preparation, warmed forward pass, training updates and evaluation separately. Synchronize accelerator work around timed regions using the chosen framework’s supported mechanism. Report peak process memory and framework allocation separately; parameter bytes exclude activations, gradients, optimizer state and input buffers. On a shared machine, begin with a single CPU worker and a small batch rather than claiming all available resources.
A closer look at the implementation
The code that carries the idea
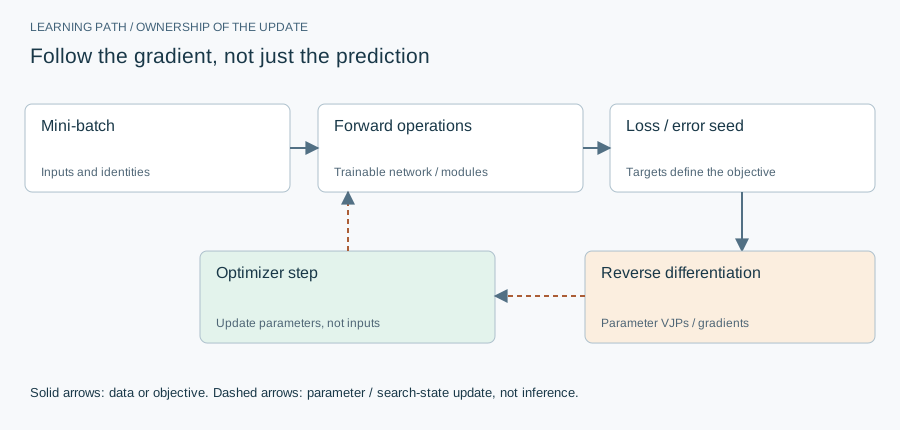
The excerpt selects only the Q value of the action actually taken using gather. The target is computed under no_grad, with the done flag removing the next-state term at episode termination. Gradients therefore update the online prediction without differentiating through the target estimate.
        states = states.reshape(self.batch_size, -1, self.state_dim)
        next_states = next_states.reshape(self.batch_size, -1, self.state_dim)

        current_q_values = self.policy_net(states).gather(1, actions.unsqueeze(1))

        with torch.no_grad():
            next_q_values = self.target_net(next_states).max(1)[0]
            target_q_values = rewards + (1 - dones) * self.gamma * next_q_values

        loss = nn.MSELoss()(current_q_values.squeeze(), target_q_values)
        self.optimizer.zero_grad()
        loss.backward()
        self.optimizer.step()
Verbatim archive excerpt from pt_drl.ipynb. Context-dependent historical code, not a standalone runnable program. Comments retain their original wording; the article distinguishes implemented behavior from stale or overbroad comments.
The boundary that matters
Reshaping a vector into a sequence does not create meaningful temporal context. The observation builder must already encode that ordering. Saved episodes demonstrate that the loop ran; they do not establish that the environment’s reward or fill model matches a real system.