The architecture in context
The system we are building
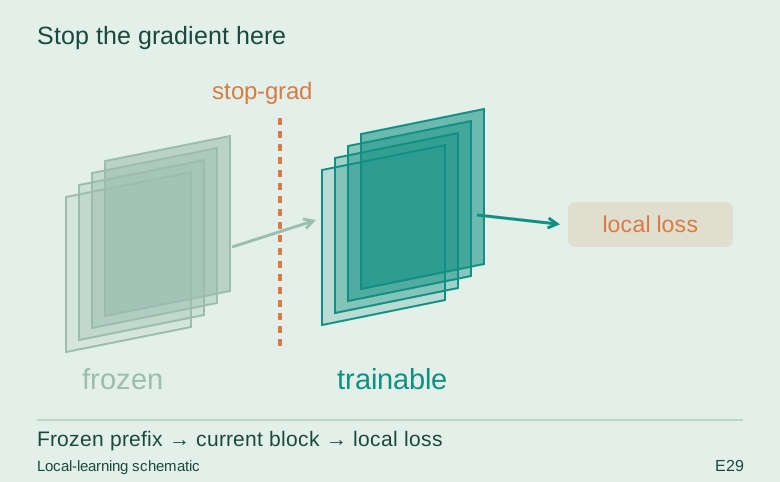
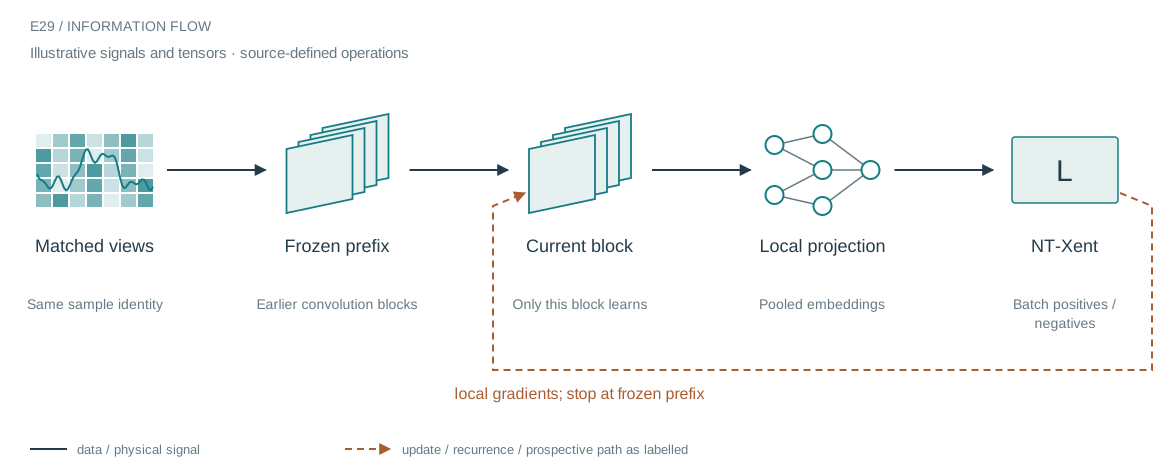
The experiment builds a hierarchy without propagating a single end-to-end supervised loss through every layer. For each block, it applies the already trained prefix without gradients, learns the current block through a local contrastive head, then freezes that block before continuing. The projection head serves the local training objective rather than becoming the final classifier.
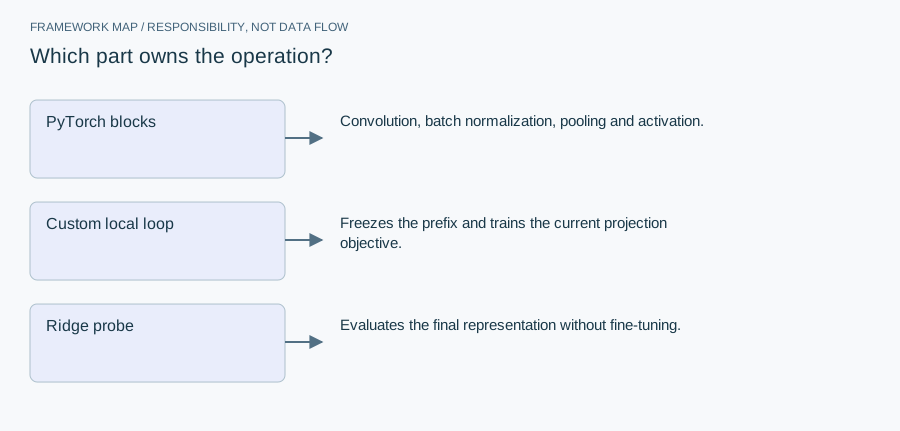
Who does what in the stack
- PyTorch blocks
- Convolution, batch normalization, pooling and activation.
- Custom local loop
- Freezes the prefix and trains the current projection objective.
- Ridge probe
- Evaluates the final representation without fine-tuning.
The custom training loop controls which modules are in evaluation mode, which parameters enter the optimizer and where gradients stop. PyTorch supplies convolution, normalization and differentiation. Locality here describes the optimization boundary, not an absence of gradients.
From module map to executable structure
Inside Greedy local contrastive CNN
CIFAR-10, three blocks with channels 32,64,128; two 3×3 convolutions per block.
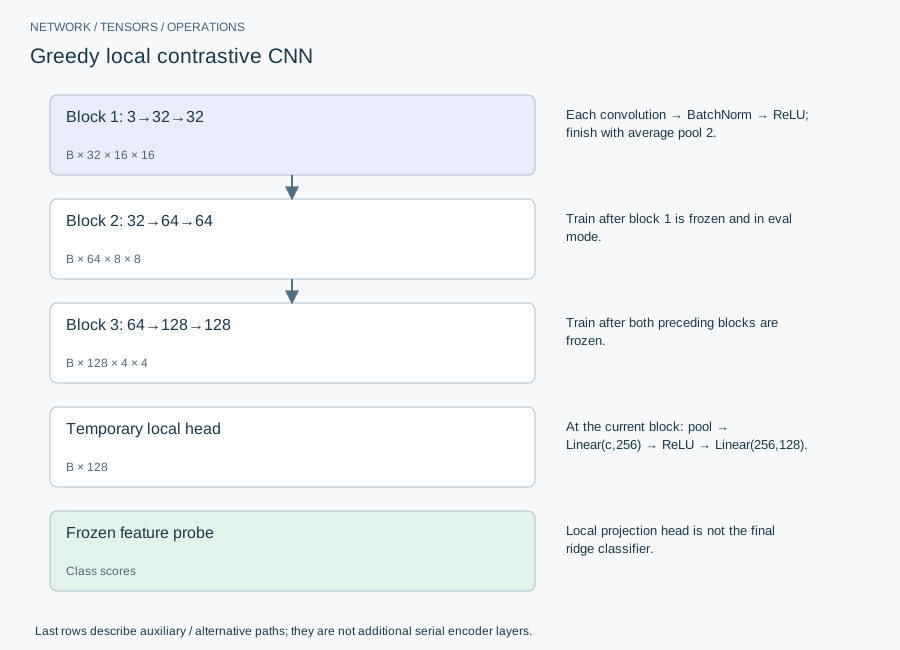
| Layer or branch | Output shape | Implementation detail |
|---|---|---|
| Block 1: 3→32→32 | B × 32 × 16 × 16 | Each convolution → BatchNorm → ReLU; finish with average pool 2. |
| Block 2: 32→64→64 | B × 64 × 8 × 8 | Train after block 1 is frozen and in eval mode. |
| Block 3: 64→128→128 | B × 128 × 4 × 4 | Train after both preceding blocks are frozen. |
| Temporary local head | B × 128 | At the current block: pool → Linear(c,256) → ReLU → Linear(256,128). |
| Frozen feature probe | Class scores | Local projection head is not the final ridge classifier. |
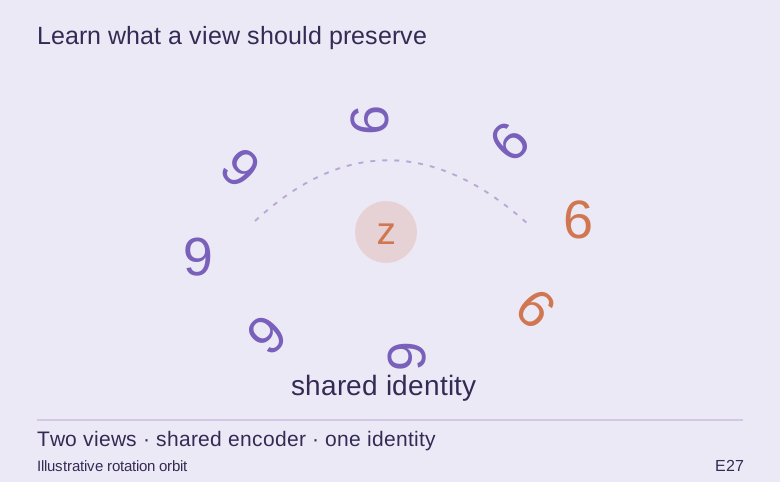
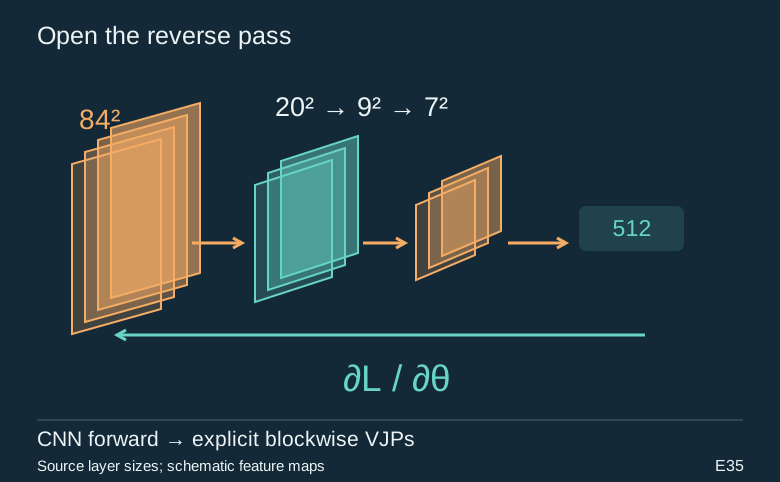
This is a different learning rule from a blockwise reverse sweep. A local loss updates only the current block and its projection head. Previously trained blocks receive neither an input gradient nor an optimizer step. The NT-Xent matrix contains 2B views, excludes self-similarity and identifies the matching view by a half-batch offset.
The equation and the update
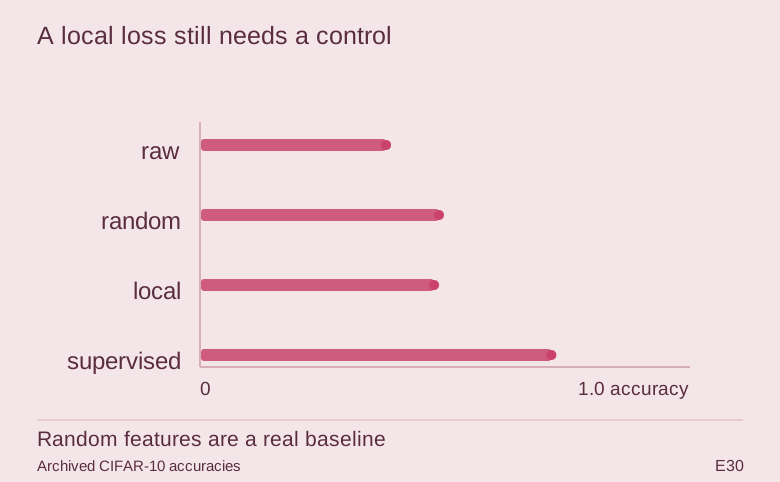
Configured 80 epochs per block, batch 512, Adam 1e-3, temperature .2; subset 20,000. The saved comparison is negative versus random convolutional features. Do not reinterpret the training budget as evidence of a benefit.
Implementation card / no invented benchmarks
Capacity, budget and execution evidence
- Parameters / retained state
- 287,904 backbone scalars. Each temporary projection head adds 256(c+1)+128×257; heads are not all simultaneously trained.
- Duration and hardware evidence
- E30 records 326.8 seconds for its saved experiment on MPS; this is not a per-block or per-epoch timing and does not identify the current workstation.
- Source coordinates
- E29 lines 24–25 and 50–84
- Current reproduction context
- Current workstation, supplied by the author: Apple M4, 128 GB unified RAM, 40 GPU cores and 16 CPU cores. This is context for prospective reproduction, not attribution of every archived run. Python and framework versions are not fully locked for these historical sources; declarations, when available, are identified separately.
Counts above are calculated from the stated layer shapes unless identified as saved measurements. They exclude optimizer state and nontrainable buffers. No archived training was rerun for this revision.
What these design choices change
Greedy freezing can reduce simultaneously trainable state but may discard information that later blocks need. A useful local contrastive objective is not automatically a useful end-to-end representation. The supervised and random-feature controls are necessary to interpret the negative result.
Reproduction and measurement protocol
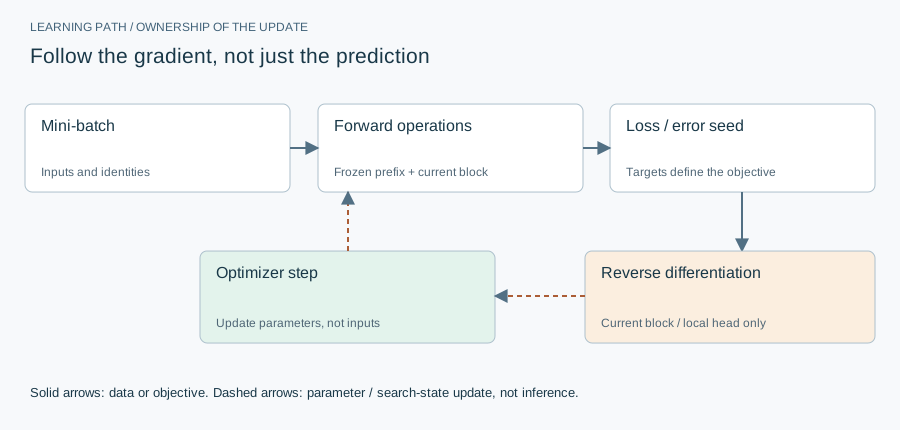
After one optimizer step, compare every earlier block’s parameters and BatchNorm buffers byte-for-byte. Check that only the current block and projection head move. A zero parameter gradient is insufficient if running statistics continue changing.
For a new run, save the resolved Python/framework versions, backend, dtype, seed, input shapes, batch size and exact source revision. Start with one batch and one update. Log training steps separately from epochs or environment steps. Do not equate the configured maximum with a completed budget or convergence.
Measure initialization/compilation, data preparation, warmed forward pass, training updates and evaluation separately. Synchronize accelerator work around timed regions using the chosen framework’s supported mechanism. Report peak process memory and framework allocation separately; parameter bytes exclude activations, gradients, optimizer state and input buffers. On a shared machine, begin with a single CPU worker and a small batch rather than claiming all available resources.
A closer look at the implementation
The code that carries the idea
The excerpt evaluates prior blocks under no_grad and trains only the current block/head pair. Evaluation mode is important as well as no_grad: otherwise running normalization statistics could change in a supposedly frozen prefix. Later layers inherit whatever information earlier local objectives preserve.
def train_unsup_local(Xtr):
    """Greedy: train each block on a LOCAL contrastive loss; input = frozen prev blocks; NO global backward."""
    blocks = []; N = len(Xtr)
    for bi, cout in enumerate(CH):
        cin = 3 if bi == 0 else CH[bi - 1]
        blk = block(cin, cout).to(DEV); head = proj_head(cout).to(DEV)
        opt = torch.optim.Adam(list(blk.parameters()) + list(head.parameters()), 1e-3)
        for ep in range(EP_BLOCK):
            pm = torch.randperm(N, device=DEV)
            for i in range(0, N, BS):
                idx = pm[i:i + BS]; xb = Xtr[idx]
                v1, v2 = augment(xb), augment(xb)
                with torch.no_grad():
                    for pblk in blocks: v1 = pblk(v1); v2 = pblk(v2)            # frozen previous blocks (detached)
                opt.zero_grad(); loss = nt_xent(head(blk(v1)), head(blk(v2))); loss.backward(); opt.step()
        for p in blk.parameters(): p.requires_grad_(False)
        blk.eval(); blocks.append(blk)
        print(f"  [unsup-local] block {bi} (ch {cout}) trained, last loss={loss.item():.3f}", flush=True)
    return blocks
Verbatim archive excerpt from closed_form_neat_biolocal.py. Context-dependent historical code, not a standalone runnable program. Comments retain their original wording; the article distinguishes implemented behavior from stale or overbroad comments.
The boundary that matters
Local objectives need not align with the final task. A low contrastive loss at each layer does not guarantee useful class features after composition. The saved CIFAR-10 result is discussed separately rather than being implied by the architecture.