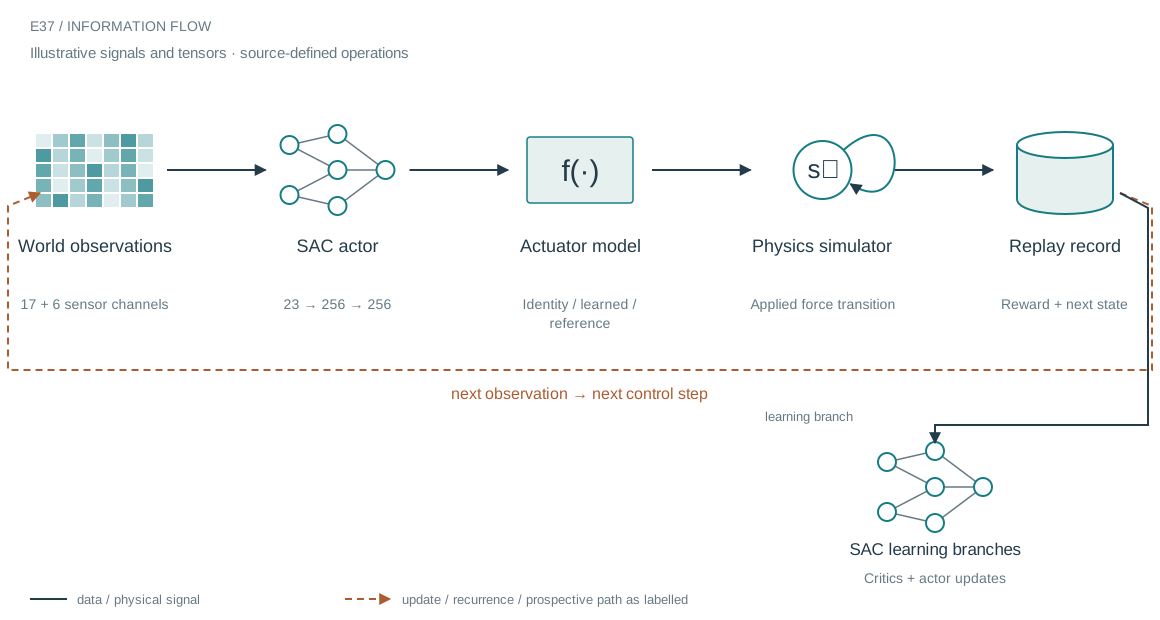
The architecture in context
The system we are building
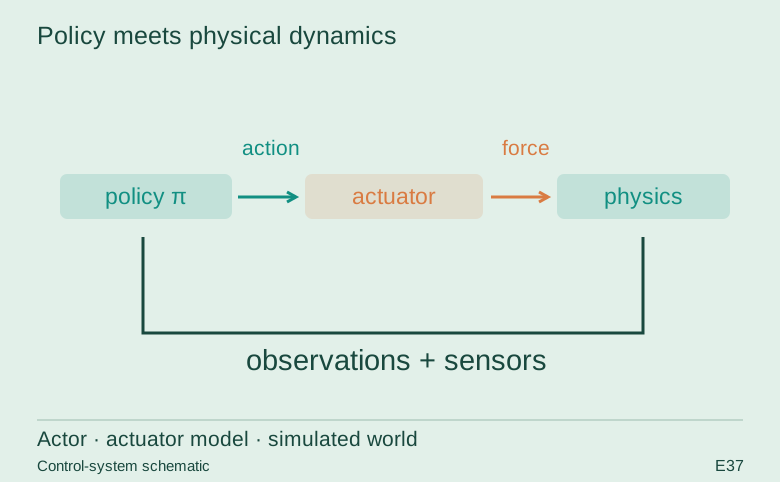
A policy learns through the environment it experiences. If the actuator transforms a command before it reaches the physical transition, then actuator mismatch is part of the control problem. This experiment wraps alternative actuator laws behind one environment interface and trains SAC policies against them.
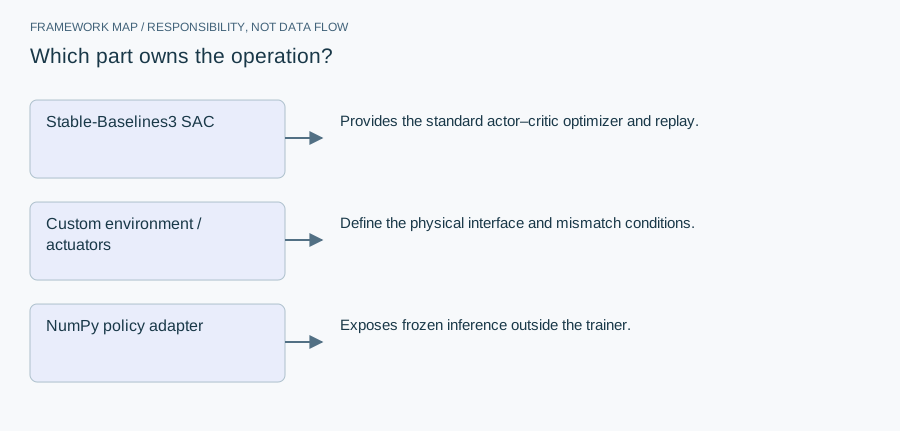
Who does what in the stack
- Stable-Baselines3 SAC
- Provides the standard actor–critic optimizer and replay.
- Custom environment / actuators
- Define the physical interface and mismatch conditions.
- NumPy policy adapter
- Exposes frozen inference outside the trainer.
Stable-Baselines3 supplies SAC’s actor–critic machinery. The project adds actuator adapters and expands a pretrained checkpoint from 17 observations to 23 by introducing six measured-force channels. New input weights start at zero, so those channels do not immediately disrupt the inherited affine computation. A NumPy policy adapter supports independent inference inspection.
From module map to executable structure
Inside SAC policy with added sensor channels
Observation grows 17→23; action dimension 6; actor and twin critics have two 256-unit ReLU layers.
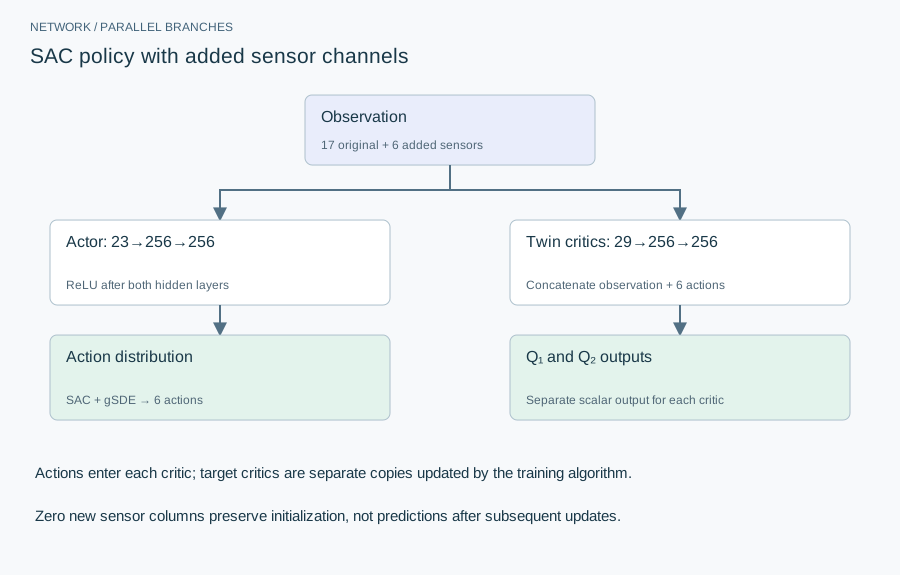
| Layer or branch | Output shape | Implementation detail |
|---|---|---|
| Observation + sensors | B × 23 | Original 17 coordinates plus 6 added sensor values. |
| Actor trunk | B × 256 | Linear 23→256 ReLU → Linear 256→256 ReLU. |
| Action distribution | B × 6 | SAC policy distribution; gSDE is enabled in the configured library policy. |
| Twin critic trunks | Each B × 256 | Each receives 23 observations +6 actions =29; two 256-unit ReLU layers. |
| Two Q outputs | Each B × 1 | Critic losses and entropy-regularized actor objective; target critics are separate. |
Zero initialization preserves the first-layer output at the instant of expansion. For critics, action columns must move past the new observation columns; simply appending zeros would mix sensor and action meaning. Actor and critic branches are parallel consumers of the observation, not one sequential network.
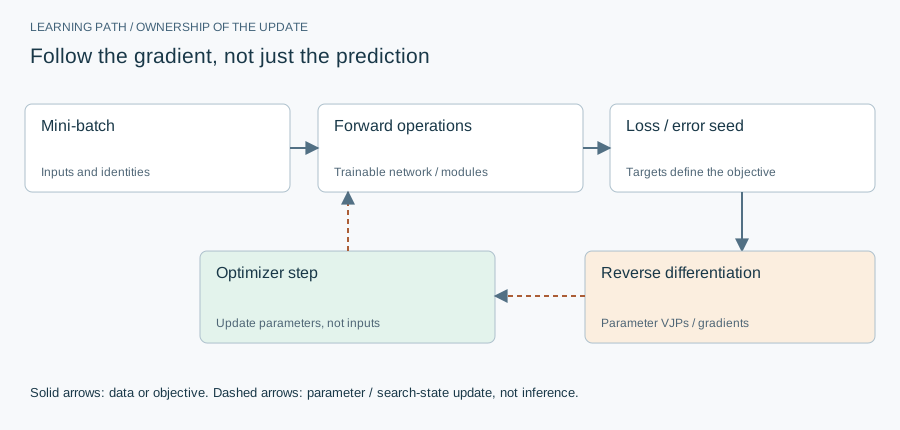
The equation and the update
SAC configured learning rate 1e-4, replay 100,000, batch 256, learning_starts 1,000, gamma .99, tau .005, train_freq 1 / gradient_steps 1, automatic entropy initialized .01; gSDE frequency 4 and warm-up enabled.
Implementation card / no invented benchmarks
Capacity, budget and execution evidence
- Parameters / retained state
- Expansion adds 1,536 input weights to actor and each critic first layer; policy-distribution parameters, both critics and target critics must also be counted. No unsupported whole-policy total is supplied.
- Duration and hardware evidence
- The gate/report, not generic M4 hardware specifications, defines the recorded training budgets. No physical-robot timing is claimed.
- Source coordinates
- E37 lines 83–111; E38 execution gate; E39 report
- Current reproduction context
- Current workstation, supplied by the author: Apple M4, 128 GB unified RAM, 40 GPU cores and 16 CPU cores. This is context for prospective reproduction, not attribution of every archived run. Python and framework versions are not fully locked for these historical sources; declarations, when available, are identified separately.
Counts above are calculated from the stated layer shapes unless identified as saved measurements. They exclude optimizer state and nontrainable buffers. No archived training was rerun for this revision.
What these design choices change
A function-preserving initialization is useful when loading a pretrained controller, but it is not a guarantee after optimizer updates. New sensor columns start with zero influence, yet can acquire gradients from the first update. Optimizer state and target-network mapping must be reconciled independently of parameter shape.
Reproduction and measurement protocol
Compare old and expanded actor outputs with added sensors set to zero. Repeat for critics using arbitrary actions, then nonzero added sensors: initial equality should still hold because those columns are zero. The simulation study’s failed acceptance gates remain failures even if this checkpoint transformation is algebraically correct.
For a new run, save the resolved Python/framework versions, backend, dtype, seed, input shapes, batch size and exact source revision. Start with one batch and one update. Log training steps separately from epochs or environment steps. Do not equate the configured maximum with a completed budget or convergence.
Measure initialization/compilation, data preparation, warmed forward pass, training updates and evaluation separately. Synchronize accelerator work around timed regions using the chosen framework’s supported mechanism. Report peak process memory and framework allocation separately; parameter bytes exclude activations, gradients, optimizer state and input buffers. On a shared machine, begin with a single CPU worker and a small batch rather than claiming all available resources.
A closer look at the implementation
The code that carries the idea
The excerpt expands actor weights from 256×17 to 256×23. The critic is subtler: its inputs concatenate observations and actions, so old action columns must move past the six new sensor columns. Copying the old matrix into the first columns would scramble that interface. The code handles actor, critic and target critic explicitly, then loads the state strictly.
    source=load_file(WEIGHTS); state=policy.state_dict(); updated={}
    for key,tensor in state.items():
        source_key=key
        if key.startswith('critic_target.') and key not in source: source_key=key.replace('critic_target.','critic.',1)
        value=source[source_key]
        if tuple(value.shape)==tuple(tensor.shape): expanded=value
        elif key=='actor.latent_pi.0.weight':
            assert tensor.shape==(256,23) and value.shape==(256,17)
            expanded=np.zeros((256,23),dtype=np.float32); expanded[:,:17]=value
        elif key.startswith(('critic.','critic_target.')) and key.endswith('.0.weight'):
            assert tensor.shape==(256,29) and value.shape==(256,23)
            expanded=np.zeros((256,29),dtype=np.float32); expanded[:,:17]=value[:,:17]; expanded[:,23:]=value[:,17:]
        else: raise ValueError(f'Unexpected checkpoint shape: {key}')
        updated[key]=torch.as_tensor(np.array(expanded,copy=True),device=tensor.device,dtype=tensor.dtype)
    policy.load_state_dict(updated,strict=True)
Verbatim archive excerpt from locomotion_policy_learning333.py. Context-dependent historical code, not a standalone runnable program. Comments retain their original wording; the article distinguishes implemented behavior from stale or overbroad comments.
The boundary that matters
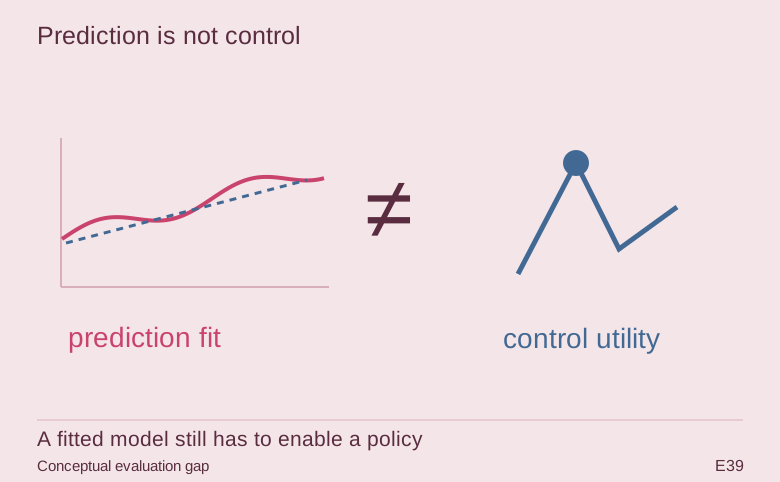
The experiments use simulated locomotion and declared actuator laws. They are not physical robot deployments. A low one-step model error is insufficient if the policy exploits inaccuracies over a long rollout; the capability result is reported in E39.