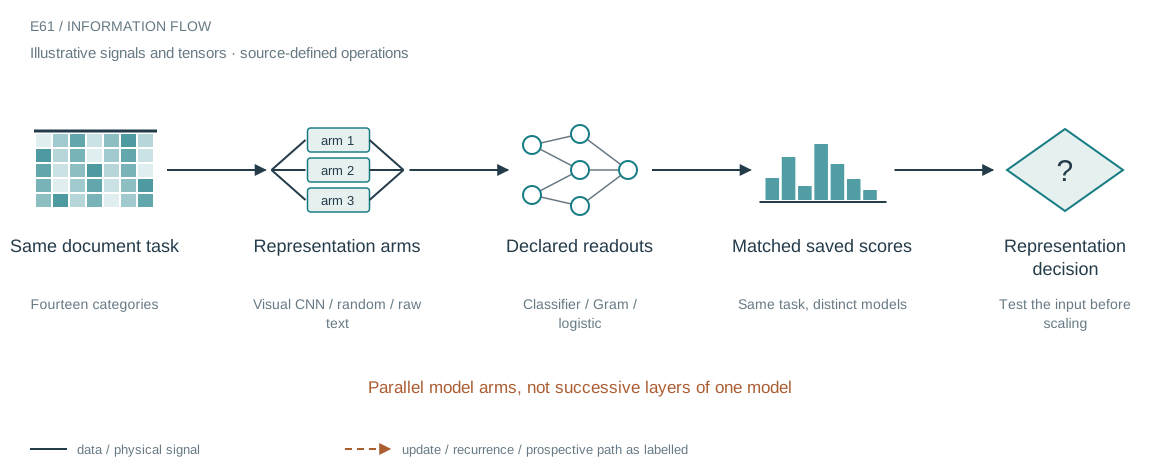
The architecture in context
What this comparison asks
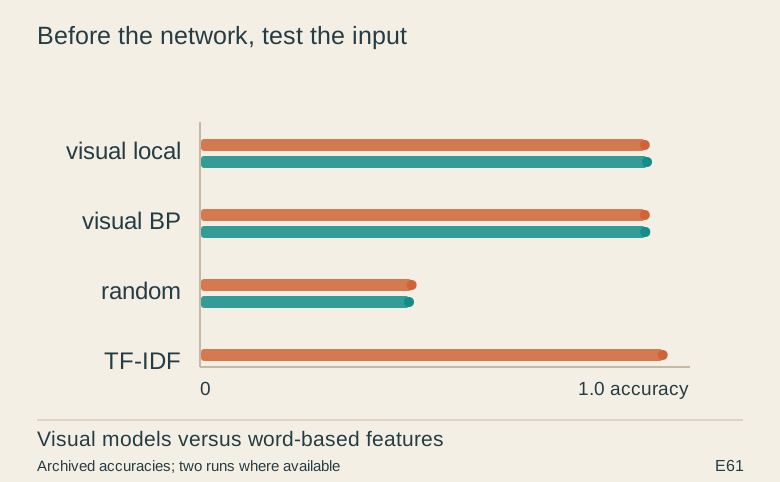
The saved experiment separates two questions: does the custom reverse schedule train the visual network, and is rendering text into pixels a good representation for this task? The local-reverse and backpropagation arms are close in the recorded runs, while the text-native control reaches the highest recorded accuracy.
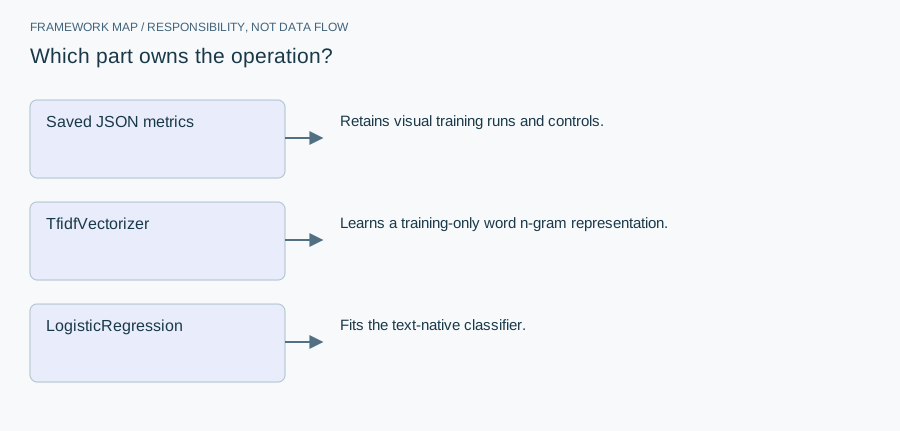
Who does what in the stack
- Saved JSON metrics
- Retains visual training runs and controls.
- TfidfVectorizer
- Learns a training-only word n-gram representation.
- LogisticRegression
- Fits the text-native classifier.
The result file preserves both visual runs and a random-feature Gram control. The code excerpt comes from the raw-text comparator. It uses a fitted TF-IDF vocabulary and logistic regression, despite a stale comment that describes ridge and character-plus-word features. The actual constructor uses word unigrams and bigrams.
From module map to executable structure
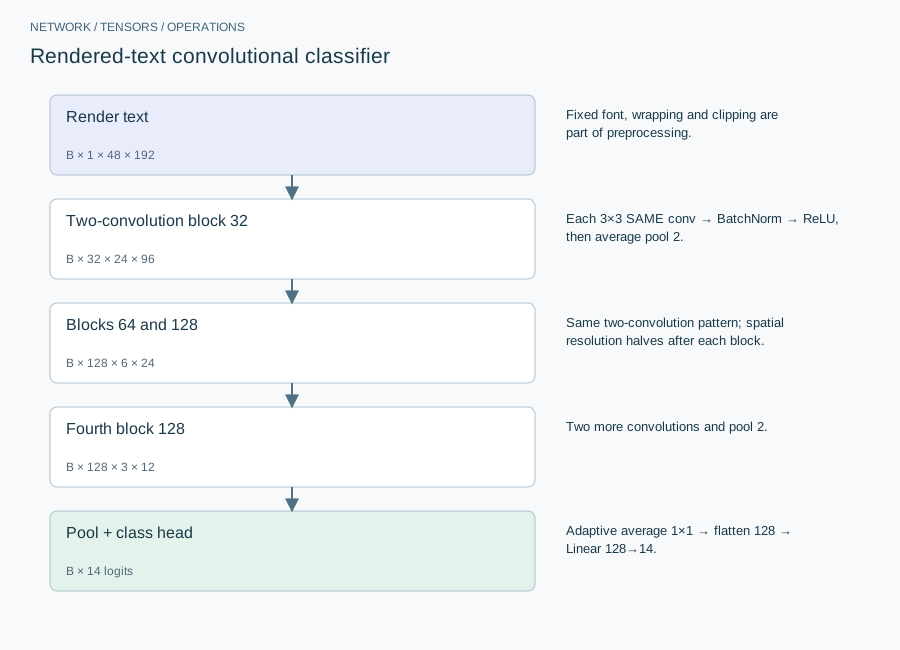
Inside Rendered-text convolutional classifier
This results or evaluation article shares the implementation in E60. The architecture below describes that companion, not a newly trained model.
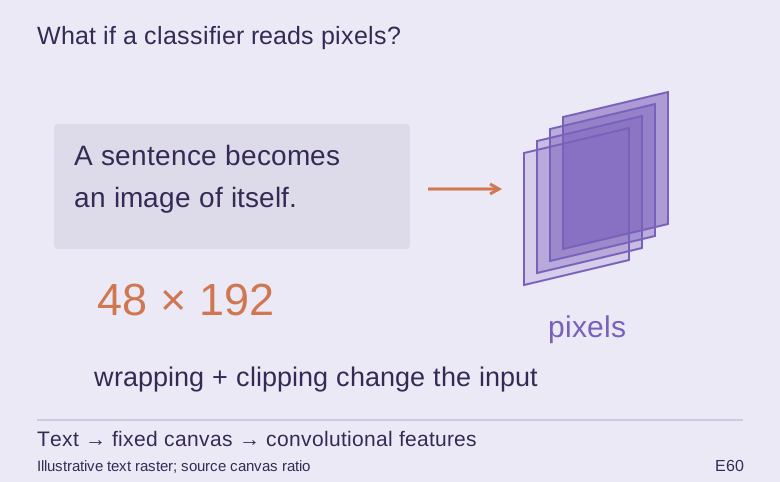
Rendered grayscale 48×192 canvas;14 classes; four blocks of widths 32,64,128,128.
| Layer or branch | Output shape | Implementation detail |
|---|---|---|
| Render text | B × 1 × 48 × 192 | Fixed font, wrapping and clipping are part of preprocessing. |
| Two-convolution block 32 | B × 32 × 24 × 96 | Each 3×3 SAME conv → BatchNorm → ReLU, then average pool 2. |
| Blocks 64 and 128 | B × 128 × 6 × 24 | Same two-convolution pattern; spatial resolution halves after each block. |
| Fourth block 128 | B × 128 × 3 × 12 | Two more convolutions and pool 2. |
| Pool + class head | B × 14 logits | Adaptive average 1×1 → flatten 128 → Linear 128→14. |
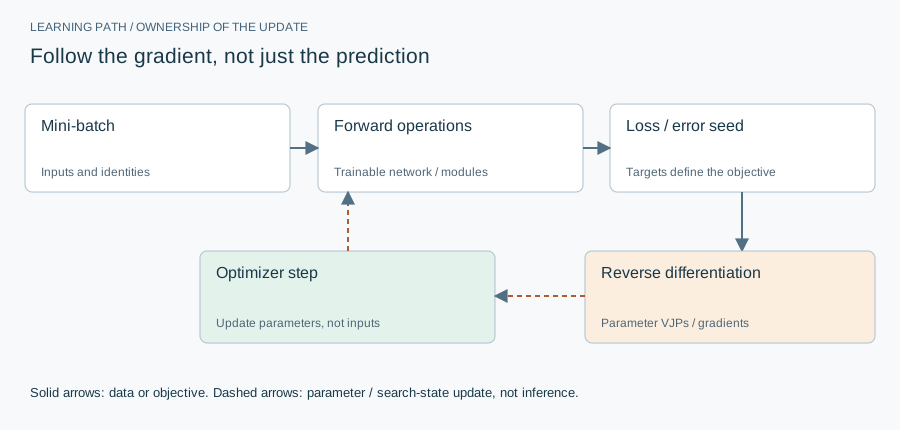
The explicit sweep changes how reverse-mode differentiation is scheduled, not the mathematical supervised objective. It still propagates a global loss gradient backward through every block. This is unlike greedy local contrastive training, which uses independent block losses and freezes preceding modules.
The equation and the update
Adam 2e-3, decay 5e-4, batch 128, cosine learning-rate schedule; configured 30 epochs,2,000 examples per class and two seeds. Compare ordinary backward with an explicit reverse VJP sweep using the same cross-entropy gradient.
Implementation card / no invented benchmarks
Capacity, budget and execution evidence
- Parameters / retained state
- 584,814 scalars, excluding BatchNorm running buffers.
- Duration and hardware evidence
- No elapsed runtime is retained in the selected saved metrics; do not infer training hours from workstation specifications.
- Source coordinates
- E60 lines 20, 58–80 and 91–105; E61 saved metrics
- Current reproduction context
- Current workstation, supplied by the author: Apple M4, 128 GB unified RAM, 40 GPU cores and 16 CPU cores. This is context for prospective reproduction, not attribution of every archived run. Python and framework versions are not fully locked for these historical sources; declarations, when available, are identified separately.
Counts above are calculated from the stated layer shapes unless identified as saved measurements. They exclude optimizer state and nontrainable buffers. No archived training was rerun for this revision.
What these design choices change
Rendering makes familiar CNN tools applicable but truncates and spatially rearranges text. The TF-IDF control operates on words and word bigrams without paying for a pixel representation. Its stronger saved result is informative: a more elaborate neural input representation is not automatically the better engineering choice.
Reproduction and measurement protocol
Keep a long-text clipping test and a font-availability check next to model tests. Compare gradients before optimizer updates, with identical model state and BatchNorm behavior. Report the word-based logistic-regression baseline as its actual algorithm, not the stale character/ridge description in a comment.
For a new run, save the resolved Python/framework versions, backend, dtype, seed, input shapes, batch size and exact source revision. Start with one batch and one update. Log training steps separately from epochs or environment steps. Do not equate the configured maximum with a completed budget or convergence.
Measure initialization/compilation, data preparation, warmed forward pass, training updates and evaluation separately. Synchronize accelerator work around timed regions using the chosen framework’s supported mechanism. Report peak process memory and framework allocation separately; parameter bytes exclude activations, gradients, optimizer state and input buffers. On a shared machine, begin with a single CPU worker and a small batch rather than claiming all available resources.
A closer look at the implementation
The code that carries the idea
fit_transform learns the vocabulary on training documents; transform applies that vocabulary to test documents. The saved local-reverse accuracies are 0.9342 and 0.9390, backpropagation 0.9342 and 0.9354, random Gram 0.4434 and 0.4379, and TF-IDF 0.9719.
def tfidf_text(txt_tr, ytr, txt_te, yte):
    """Honesty ceiling: TF-IDF char+word n-grams + ridge on the RAW TEXT (what text-native NLP gets)."""
    try:
        from sklearn.feature_extraction.text import TfidfVectorizer
        from sklearn.linear_model import LogisticRegression
    except Exception as e:
        return None
    v = TfidfVectorizer(max_features=50000, ngram_range=(1, 2), sublinear_tf=True)
    Xtr = v.fit_transform(txt_tr); Xte = v.transform(txt_te)
    clf = LogisticRegression(max_iter=300, C=10.0); clf.fit(Xtr, ytr.numpy())
    return round(float((clf.predict(Xte) == yte.numpy()).mean()), 4)
Verbatim archive excerpt from closed_form_neat_textvision.py (companion source E60). Context-dependent historical code, not a standalone runnable program. Comments retain their original wording; the article distinguishes implemented behavior from stale or overbroad comments.
The saved comparison
Archived results, not new training. The article states the comparison’s scope and limitations.
| Arm | Run 1 | Run 2 |
|---|---|---|
| Visual local reverse | 0.9342 | 0.9390 |
| Visual backprop | 0.9342 | 0.9354 |
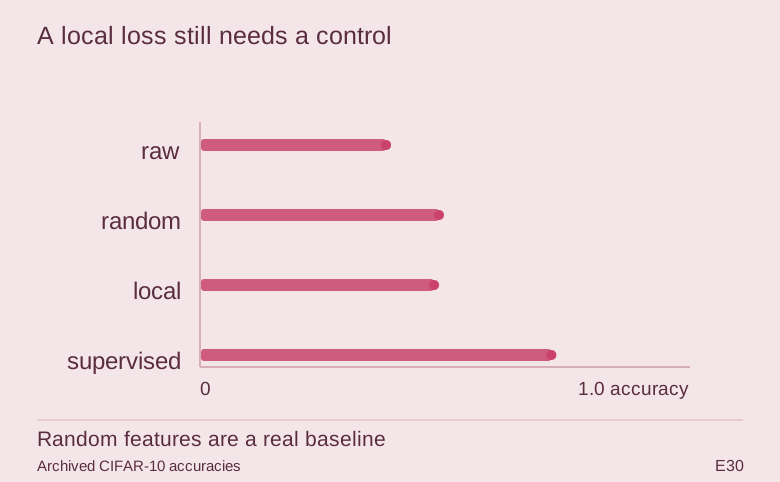
| Random visual Gram | 0.4434 | 0.4379 |
| Text TF-IDF | 0.9719 | Not separately recorded |
The boundary that matters
The visual methods’ closeness is not evidence that either improves on the text-native representation, and two saved runs are not an equivalence test. The result is useful because it prevents optimizer novelty from distracting from a stronger, simpler input representation.